Видео с ютуба Single Stream Inference

LLM Inference Is a Memory Problem, Not a Compute One
How AI Models Scale Beyond a Single GPU Across LLM Workloads
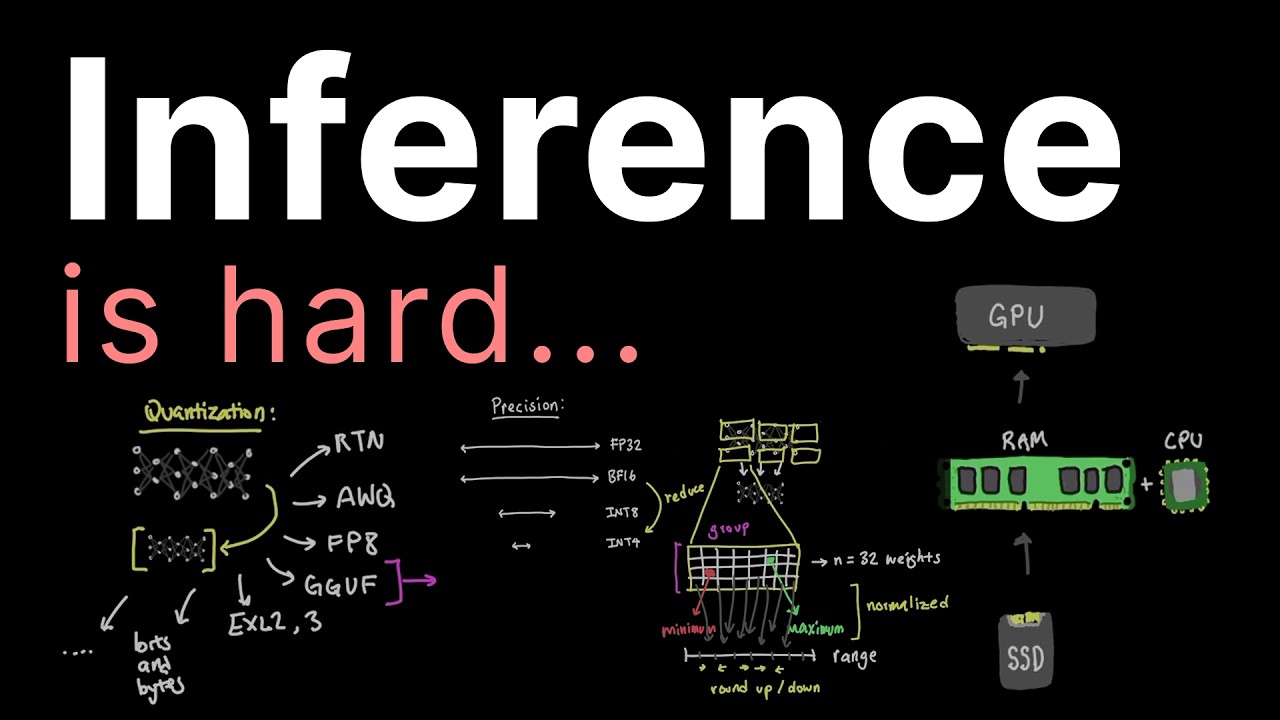
Почему делать логические выводы сложно...

Учебное пособие по Amazon Bedrock: Выполнение LLM-выводов в одиночном и пакетном режимах на Amazon.

What Is LLM Inference? How AI Models Generate Responses

AirLLM: Layer-Wise Inference Mechanism for Running Large Parameter LLMs on a Single 4GB GPU
Поставщики выводов: лучший способ разработки с использованием моделей с открытым исходным кодом

Глава 3.5 – Урок 1/3 – Вывод для одной пропорции

NInfer GitHub Explained: Single-GPU Qwen Inference on the RTX 5090

Inference Engineering Is the Most Important AI Skill Right Now: The 4-Layer Stack

Deep Dive: Optimizing LLM inference

Run A Local LLM Across Multiple Computers! (vLLM Distributed Inference)

What Is an Inference Engine? DeepSeek Just Open-Sourced One

AI Inference: The Secret to AI's Superpowers

Best AI Inference Providers in 2026: fal vs Baseten vs Together vs Fireworks vs Modal